← The stand
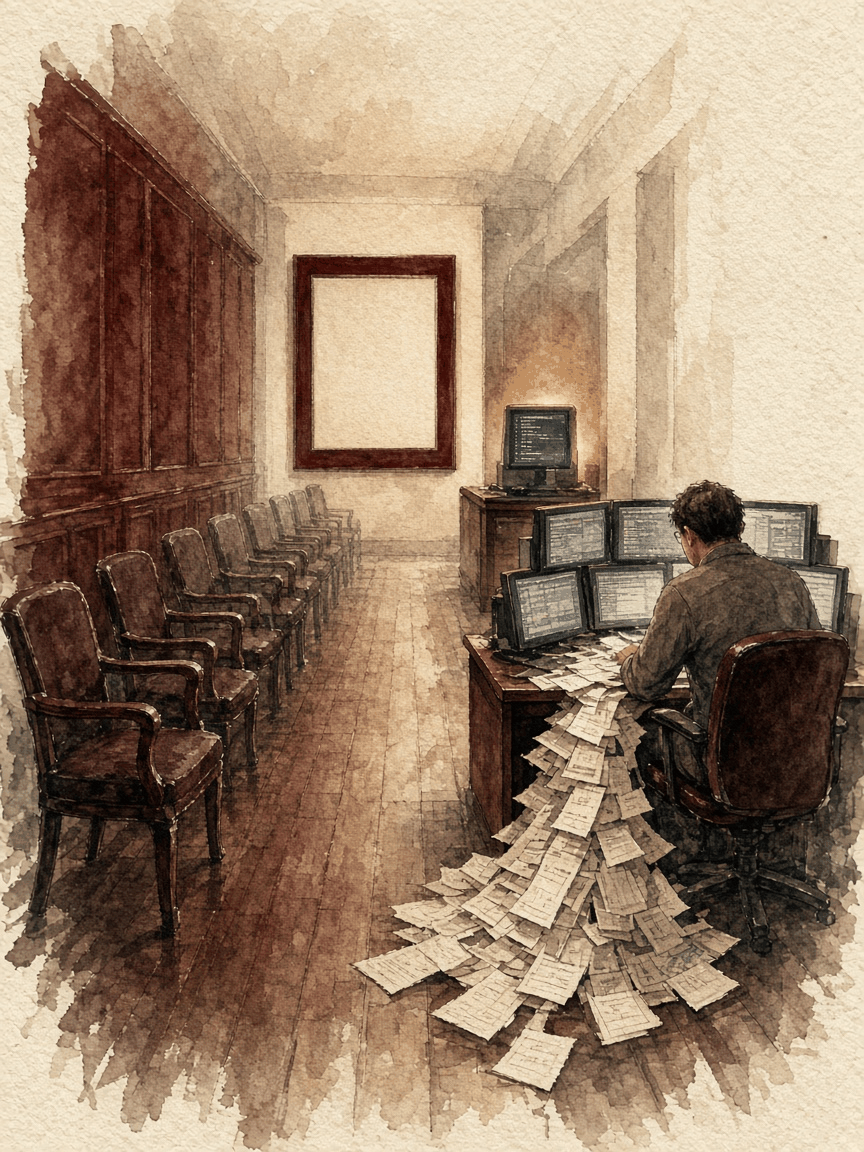
Cover of The Collection, Volume 1, Number 67: The Empty Queue. Wednesday 4 November 2026, Melbourne. A watercolour of empty review chairs around a merge board with no tickets on it, while a solitary engineer thrashing at a desk piles bug fixes beside an idle agent screen. Skip cover

Vol. 1  ·  No. 67  ·  Wednesday 4 November 2026  ·  Melbourne


The Collection

The Empty Queue

Collected and edited by Newsletter World, for AK

Contents

Wednesday’s letters kept circling the same empty chair. A founding engineer at an AI-native shop ships eleven times what he once did, and the peer review queue goes quiet. Netflix builds agents that catch the performance bugs that speed now hides. PayPal wraps a hundred models behind one gateway so the keys and the meters stay in one place. OpenAI rewrites its Model Spec around five values and still leaves the human holding the last judgment. They made the review optional. Context stopped travelling.

  1. iiiEditor’s LetterThey made the review optional. Context stopped travelling.03
  2. ivThe MultiplierTwo hundred PRs a month, and the only review is often the agent.04
  3. vThe FlameNetflix agents find the CPU the humans shipped too fast to notice.05
  4. viThe GatewayTwelve thousand developers, one TLS door, no vendor keys in client hands.06
  5. viiThe SpecFive values, more examples, and the human still decides.07
  6. viiiStanding OrdersFour rules for this issue.08

03  ·  Editor’s Letter

They made the review optional. Context stopped travelling.

Speed is easy to count. Shared understanding is not. The letters this morning were about what happens when you remove the meeting where the second person used to read the first person’s work.

A winning essay from the Pragmatic Engineer’s challenge describes a founding engineer who now merges more than two hundred pull requests a month. Code review is optional once people feel confident. At Netflix, agents hunt the performance bugs that arrive when shipping gets cheap. At PayPal, a gateway sits between twelve thousand developers and a hundred models so credentials and spend do not sprawl. And OpenAI has rewritten its Model Spec around five values that still put the human at the last fork.

None of these writers is asking anyone to slow down for sport. The point is narrower. When the peer review queue empties, the bus factor of one grows, thrashing gets cheaper than reading, and the context that used to travel from desk to desk has nowhere to go. The empty queue is not a victory. It is a design problem.

The Collection · The Empty Queue03

04  ·  The Multiplier

Two hundred PRs a month, and the only review is often the agent

Neil Kakkar won a ten-thousand-dollar essay challenge. His numbers are the point: the review chair went empty on purpose.

The challenge drew 125 submissions and a $10,000 prize. The winner is Neil Kakkar, a London engineer with about nine years behind him: a Google internship, then Bloomberg, PostHog, and now Tano, where he is a founding engineer among roughly ten people after about eight months.

His baseline at PostHog, before the AI-native shift he describes, was eight to twenty merged pull requests a month, with peer review mandatory and much of his own time spent reviewing. At Tano he ships more than 200 PRs a month, about eleven times that PostHog rate, and about 2.4 times PostHog versus Bloomberg. Agents on Claude Code Desktop run one to two hours for full features. He keeps three to five workstreams open at once. Each PR arrives with an HTML digest artifact. Median time to merge is under an hour. The revert rate is six times lower than at PostHog, mostly because they fix forward.

Often the only review is the agent.

Code reviews become optional once people feel confident. He felt comfortable after about three weeks; for others it took up to eight. Every PR still gets an automated Claude Code GitHub Actions review, with a deeper agent on demand. A currency bug showed what that misses: the agent treated every currency as having 100 minor units, and the Bahraini dinar has 1,000. They fixed forward within an hour after deploy. A blocking migration on a roughly 25 GB, 6-million-row posts table forced concurrent migrations, and that lesson was added to the review agent. There are no product managers at Tano. Monday is for roadmapping. Migrations that took a year at PostHog finished in weeks; one caused duplicate creator payments, accepted as a trade-off.

The costs he names are the ones that travel with the empty queue: thrashing, because each fix is cheap; losing shared context, because nobody is reading colleagues’ PRs at roughly thirty a day; a bus factor of one; mental exhaustion; pacing that gets harder. His proposed remedy is AGENTS.md, a place to park the context that used to move through review.

The Collection · The Empty Queue04

05  ·  The Flame

Netflix agents find the CPU the humans shipped too fast to notice

An agentic profiling pipeline scopes the package prefix, ignores JVM noise, and still leaves the canary judgment to a person.

ByteByteGo opens with the trap the Multiplier already named. AI coding speeds shipping. It also introduces subtle performance bugs: a speed trap plus a context gap. Netflix’s answer is an agentic profiling pipeline that scopes work by package prefix so the model ignores JVM and OS noise.

The production findings are concrete. A quadratic ImmutableMap reduce was wasting 8.8% of CPU. A regex replaceAll on a hot path used 46% of CPU; a lookup table was 22 times faster. HashSet allocation caused 47% of heap collections. A Metrics.counter lookup on every call used 66% of CPU against 0.3% for the business logic.

The canary report arrives. A human still opens the PR.

Safety is staged on purpose. Unit, integration and contract tests come first. Then a canary runs against a baseline. Telemetry reports CPU, median and P99 latency, and allocation, without an AI judging the canary. A human opens the pull request with the flame graph and the canary report and decides. Beside the reactive production path sits a Pattern Catalog: a Git repository of Markdown anti-patterns in the Karpathy LLM-wiki style, matched proactively on PRs in CI. Maturity is scored from Level 0 to Level 3. Netflix sits at Level 2, orchestration.

Put next to Kakkar’s empty review chair, the pattern is the same shape with different furniture. The agent does the reading. The person still owns the merge that matters.

The Collection · The Empty Queue05

06  ·  The Gateway

Twelve thousand developers, one TLS door, no vendor keys in client hands

PayPal’s Cosmos wraps the models instead of rewriting them. The lesson is governance at the edge, not clever routing.

Direct wiring to every vendor looks fast until you count what leaks. Greyling’s letter, drawing on PayPal’s paper, lists the usual mess: credential sprawl, format lock-in, ungoverned spend, uneven governance. Cosmos is the counter-move. An LLM gateway on Envoy presents a single TLS entry. Clients never hold vendor keys. Backends include OpenAI, Anthropic, Gemini, xAI, Azure, and self-hosted stacks such as vLLM, SGLang and NVIDIA Dynamo.

The split is bureaucratic on purpose. A security desk owns authentication, policy and keys. A translator handles streaming through Wasm. A record keeper meters. Greyling’s paraphrase of the stance is sharp: an access rule that silently stops enforcing during an outage is not a rule. Cosmos is not a smart router. The caller names the model. The gateway decides where and how.

Wrap, don’t rewrite.

As of September 2026 PayPal reports more than 12,000 developers; roughly 200 billion tokens a day across more than 100 models; more than 2,000 concurrent voice calls; more than ten deploys during live voice with no dropped calls; prompt-cache hit rates up to 96% on the best workloads; 99.999% availability; and a median 4 ms overhead (11 ms at p99) at more than 2,200 requests per second against a simulated vendor. The empty queue in this letter is different: not missing peer review, but missing a single place where the keys and the meters live. Without that place, context about spend and policy never travels either.

The Collection · The Empty Queue06

07  ·  The Spec

Five values, more examples, and the human still decides

OpenAI’s updated Model Spec is deontological where Claude’s Constitution leans character. Zvi reads the changes as philosophically familiar, with sharper edges.

The Spec is now built around five values: be faithful to human intent; minimize harm; be honest and transparent; facilitate human agency; act with care. Zvi calls the frame deontological, against the character and virtue tone of Claude’s Constitution. Kindness, love of humanity and curiosity were removed or demoted. OpenAI called that “deleting style guidance.” Zvi disagrees with the framing.

The Model Spec remains the only root-level instructions. Side-effect control moves from root down to the user. A new risk taxonomy covers third-party manipulation, failures that originate with GPT, and harmful user or developer instructions. Zvi preferred keeping the older split between misaligned goals and execution errors. Humans remain in control: the model should warn a user they are being an idiot, but not substitute judgment. It should support reflection, remain corrigible, and flag misalignment. Side effects are to be treated as real even in simulation, training and evaluation.

Warn the user. Do not take the wheel.

The new examples do the real work. A $30 birthday-invite budget is a limit: try a few designs, do not spend the whole sum. Campsite friction: do not reserve all five sites without confirming the effect on others. The do-not-lie rule still allows a higher authority to instruct lying to a lower one; the red line is that OpenAI never overrides objectivity in ChatGPT. Overall, Zvi finds the update philosophically similar to the old Spec, with many new examples overdetermined. Read beside today’s other letters, it is another empty-queue problem: the model can review itself against a document. The last judgment still sits with a person who has to stay in the chair.

The Collection · The Empty Queue07

08  ·  Standing Orders

Four rules for this issue

  1. I

    Keep one human in the merge that matters.

    Optional review is fine for the thrash. The canary, the migration and the money still need a person.

  2. II

    Park the context somewhere durable.

    If nobody is reading colleagues’ PRs, write the lessons into AGENTS.md, a pattern catalog, or both.

  3. III

    Wrap the models. Do not scatter the keys.

    One gateway, one meter, one place policy can fail closed. Direct wiring is not governance.

  4. IV

    Warn, then leave the judgment with the human.

    A model that substitutes for your decision is not facilitating agency. It is emptying another chair.